AI Course for Beginners: Compare Two Answers Fairly
Use the SAME comparison card to test two AI answers with one task, one input and one success rule—then choose by evidence, not polish.
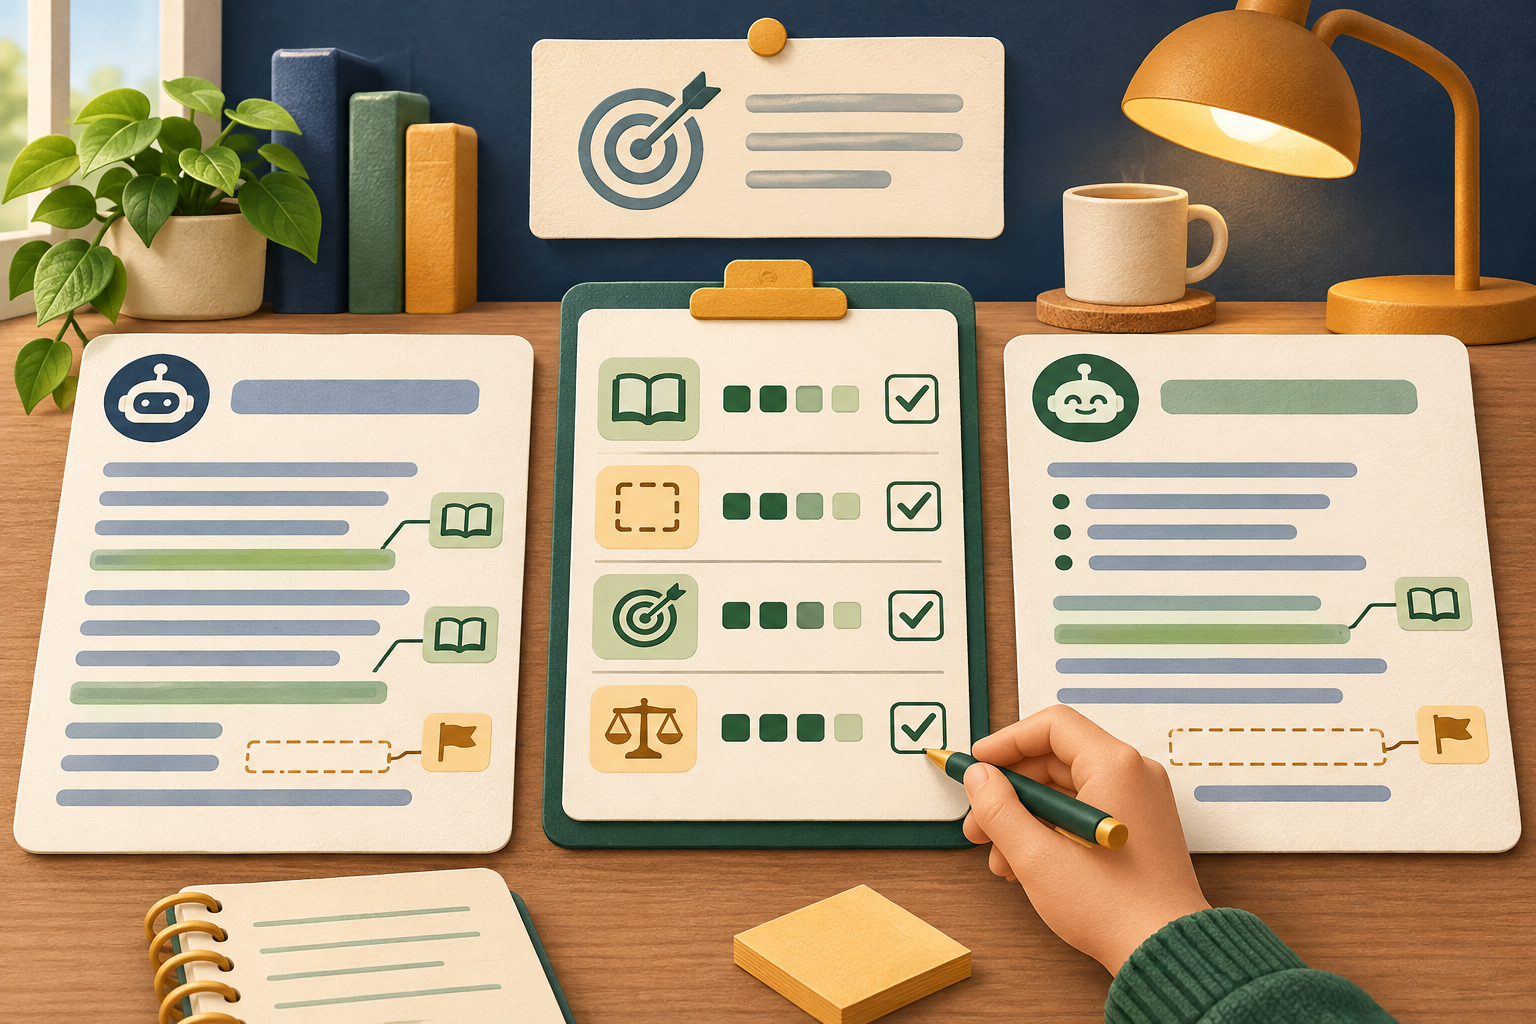
An AI course for beginners should teach how to compare two answers fairly, not how to pick the one that sounds most confident. If the task, input and success rule change between attempts, the comparison tells you almost nothing. If they stay fixed, you can see which answer is more accurate, complete and useful for the work.
The goal is not to crown a universal winner. It is to build a repeatable judgement habit: give two answers the same test, mark their evidence and omissions, then explain which one you would use and what still needs checking.
Why an AI course for beginners needs a fair comparison rule
Current public guidance from British Columbia tells users to review generative-AI outputs for relevance, accuracy, consistency, audience fit and bias, and to verify important details against reliable sources. The UK Government AI Playbook similarly says AI is not guaranteed to be accurate and that users need a process to test outputs. NIST’s Generative AI Profile provides a risk-management resource for evaluating generative AI in context.
For a beginner, those principles can feel abstract. The mistake is often simple: the first answer gets a vague prompt, the second gets extra context, and the more polished reply wins. That is not a fair comparison. It is two different tasks.
The SAME comparison card
S — Set the task and success rule
Write one bounded task, intended audience and four things a usable answer must contain.
A — Apply the same input
Use the same source pack, prompt and constraints for both answers. Start fresh sessions when context could leak across attempts.
M — Mark evidence and omissions
Underline supported claims, circle items that need verification and list required content that is missing.
E — Explain the choice
Choose with the fixed rule, record the reason and name the checks or edits still required.
Compare the work, not the writing style
Suppose a new operations coordinator must turn a public meeting note into a short internal action summary. The success rule is fixed before generation: name the decision, the owner, the deadline and the unresolved question. The same note and prompt go into two fresh AI chats.
Answer A is smooth and concise. It invents a deadline from a phrase such as “as soon as practical” and assigns the task to the person who spoke most. Answer B is plainer. It records the decision, says the owner is not stated, preserves the original timing phrase and lists the unresolved question. The second answer is more usable because it respects the evidence, not because it sounds better.
| Polished answer | Work-ready answer | |
|---|---|---|
| Decision | May paraphrase confidently | Matches the source note |
| Owner | May infer a likely person | States named owner or marks the gap |
| Timing | May convert vague language into a date | Preserves the wording or requests clarification |
| Missing item | Can hide it in fluent prose | Makes the omission visible |
| Next step | Ready-looking draft | Draft plus explicit checks |
Reading is a start. Practice makes it stick.
Start learningRun the comparison in four short passes
A beginner-friendly review sequence
- 1
1. Freeze the test
Copy the same task, source and constraints into two fresh sessions or two approved tools.
- 2
2. Check required parts
Mark each success-rule item as present, missing or unsupported. Do not score style yet.
- 3
3. Verify one important claim
Open the source and check the claim most likely to change the decision. Follow links rather than trusting a citation label.
- 4
4. Record the choice
Write one sentence: which answer is the safer starting point, why, and what a human must still do.
Do not keep adding hints to one answer until it wins. If both fail the same requirement, improve the task or source pack and rerun both. If the work is sensitive or high consequence, stop the exercise and follow the organisation’s approved review route.
Use scores carefully
A simple present–missing–unsupported card is often better than a ten-point score. A high average can hide one critical failure, such as a fabricated source, an invented commitment or a missing safety step. Decide which failures are disqualifying before you inspect the answers.
European Commission guidance says AI-literacy actions should account for people’s knowledge and experience, the context and purpose of the system, and the risks involved. A fair comparison exercise does exactly that: it gives beginners a small, visible practice loop without pretending every task carries the same consequence.
Connect the comparison to a learning path
Start with Bokili’s guide to a reversible beginner task. Then write the expected answer first, improve through a one-mistake correction loop and learn when to stop prompting. Bokili’s HR and L&D page explains how short practice can be adapted to role and skill level.
- Choose a low-risk task with a short public source, such as a meeting note or product description.
- Write four success conditions before opening the AI tool.
- Run the identical prompt and source in two fresh sessions.
- Mark each condition as present, missing or unsupported in both answers.
- Verify the most important claim in the original source.
- Write your choice and the remaining human check in one sentence.
Build judgement through repetition
A beginner does not need dozens of tools or a long prompt library. They need a fair way to notice what changed, what is missing and what still needs proof. SAME turns comparison into a small repeatable skill. Practise it on ordinary work, keep the evidence visible and let the success rule—not the fluency—decide.
Sources
- How to review generative AI outputs — Province of British Columbia
- Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile — NIST
- Artificial Intelligence Playbook for the UK Government — UK Government
- AI Literacy — Questions & Answers — European Commission
- AI training for HR & L&D leaders — Bokili
Reading is a start. Practice makes it stick.
Bokili turns skills like this into ten-minute missions for your whole team, with instant feedback and progress you can see.
Start learningKeep reading
Use AI to Compare Supplier Proposals Without Hiding Evidence Gaps
A procurement workflow for mapping supplier responses into one fixed evidence matrix without inventing equivalence or filling missing proof.
AI Learning and Development: Run a Delayed Transfer Check
Use the TRACE method to check whether an AI skill reached real work, what evidence exists and which barrier or next practice needs attention.
Turn AI Ideas Into a Governed Use-Case Queue
Use the QUEUE method to compare AI ideas by work need, simpler alternatives, consequence, evidence and accountable ownership before a pilot starts.