Use AI to Compare Supplier Proposals Without Hiding Evidence Gaps
A procurement workflow for mapping supplier responses into one fixed evidence matrix without inventing equivalence or filling missing proof.
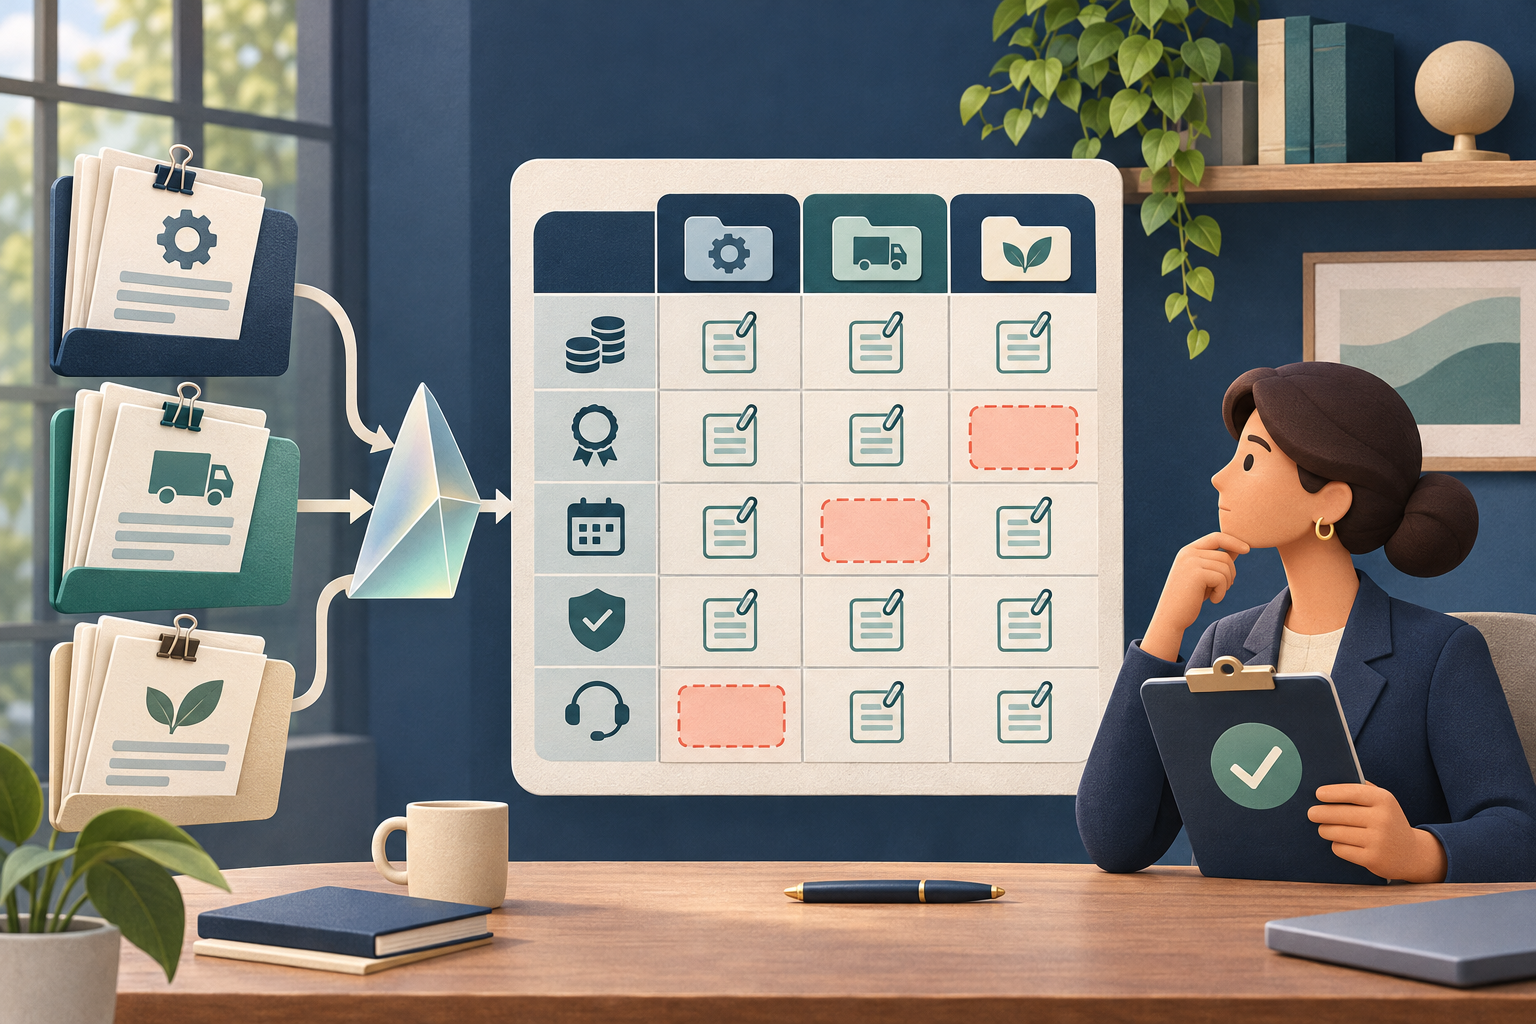
A supplier proposal can look complete because its headings are tidy, its claims are confident and its language mirrors the tender. That is exactly where an AI-assisted comparison can go wrong. The model may make three different responses look equivalent even when one contains evidence, one contains a promise and one says nothing at all.
Procurement teams can use AI to organise long responses, but not to invent comparability. The useful output is an evidence matrix that applies one fixed criterion set, links every observation to the supplier’s own response and leaves missing evidence visible. The human evaluation panel still owns the judgement, clarification route and award recommendation.
Fix the rules before AI sees the proposals
UK Government commercial guidance says supplier-selection criteria and the evaluation method should be established before offers are invited. It also says proposals should be evaluated using those defined criteria, with cross-functional support and without conflicts that could prejudice the result. Procurement Act guidance likewise treats award criteria and assessment methodology as the basis for assessing competitive tenders.
That principle matters beyond public procurement. If you let an AI tool infer the criteria from whichever proposal sounds strongest, the comparison moves after the evidence arrives. Freeze the question, scale, weighting, mandatory evidence and failure conditions first. Then use an approved AI environment only for bounded extraction and organisation.
The CLEAR evidence matrix
C — Criteria locked
Write the criterion, scoring rule and mandatory evidence before processing any proposal.
L — Link to the response
Anchor every observation to a section, page, table or exact short extract from the supplier’s submission.
E — Expose gaps
Mark missing, ambiguous and non-responsive material explicitly. A blank cell must stay blank.
A — Apply one standard
Use the same question, response format and evidence rule for every supplier.
R — Retain human judgement
Let the panel verify evidence, resolve clarifications and own every score and recommendation.
A five-step AI workflow for bid comparison
From response pack to reviewable matrix
- 1
1. Build the empty matrix
Create rows from the published criteria and columns for evidence anchor, supplier claim, gap, clarification status and evaluator note.
- 2
2. Process one supplier at a time
Give the approved tool the criterion text and only the relevant response sections. Ask for extraction, not a score.
- 3
3. Preserve the source language
Keep a short extract and its location beside any summary. Do not allow the model to strengthen words such as may, plans to or intends.
- 4
4. Run the same request again
Use the identical instruction and output schema for every proposal. Record any parsing problem rather than improvising.
- 5
5. Verify before evaluation
A procurement specialist checks every anchor and gap. Only then does the authorised panel apply the published scoring method.
The tool should not decide whether a vague sentence deserves partial credit. It should help the team see that the sentence is vague. Keep extraction and evaluation as separate stages so a polished summary cannot become an unofficial score.
Worked example: three support-service proposals
Imagine a fictional tender asks suppliers to evidence out-of-hours incident support, including coverage, response target and escalation route. Proposal A states that priority-one incidents receive 24/7 cover, names a 30-minute response target and points to an escalation table. Proposal B promises “full support whenever needed” but gives no target or route. Proposal C provides an evening rota and a two-hour target, but is silent on weekends.
Reading is a start. Practice makes it stick.
Start learning| Proposal A | Proposal B | Proposal C | |
|---|---|---|---|
| Coverage | 24/7, anchored | Claimed as full; scope unclear | Evenings stated; weekends missing |
| Response target | 30 minutes | Not stated | Two hours |
| Escalation evidence | Named table | Not stated | Named rota, no weekend path |
| Matrix treatment | Evidence recorded | Gap preserved | Partial evidence plus gap |
A weak AI summary might call all three proposals “comprehensive support”. CLEAR prevents that compression. It records what each supplier actually provided and separates missing evidence from poor performance. If the procurement rules allow clarification, the team follows that formal route consistently; it does not ask the model to fill the silence.
Use a controlled extraction instruction
A practical instruction is: “For this criterion only, extract each explicit claim and its response location. Preserve qualifiers. Do not score, infer equivalence or complete missing information. Return ‘not evidenced’ when the response does not supply the required item. Flag ambiguous wording for human review.” Keep the criterion and output fields identical across suppliers.
Do not paste confidential or commercially sensitive material into an unapproved tool. The UK Government AI Playbook emphasises using the right tool, understanding limitations, testing outputs and retaining meaningful human control. Public procurement guidance on AI transparency also shows why teams need explicit controls when AI may enter the procurement process.
Verify the matrix before anyone sees a score
Check a sample of positive findings, every negative finding and every row that could change the ranking. Confirm that the matrix has not merged criteria, normalised incompatible units or converted future plans into current capability. Record who verified each row and when. For a high-value or high-risk procurement, use the organisation’s formal assurance, legal and commercial routes.
This workflow complements Bokili’s guides to building an evidence-tagged contract obligation register, keeping marketing claims tied to evidence and turning ideas into a governed AI use-case queue. The common skill is traceability: structure helps only when a reviewer can get back to the source.
- Choose one low-sensitivity, fictional criterion and write the scoring evidence before you create any answers.
- Draft three short supplier responses: one complete, one vague and one partly complete.
- Create an empty CLEAR matrix with a source-anchor and gap column.
- Run the same extraction instruction on each response in an approved tool.
- Check whether any blank was turned into an assumption or any qualifier was strengthened.
- Rewrite the instruction until the matrix preserves every gap, then save it as a role practice template.
Make the gap reviewable
AI can reduce the clerical load of mapping long proposals into a common structure. It should not make unlike evidence look alike. A strong procurement workflow locks the criteria, preserves the source and makes every absence easy to inspect. Bokili helps teams rehearse these bounded, evidence-aware role workflows in short practical missions before they matter in live work.
Sources
- Assessing competitive tenders — UK Government Procurement Pathway
- Government Functional Standard GovS 008: Commercial — UK Government
- Guidelines for AI procurement — UK Government
- PPN 017: Improving transparency of AI use in procurement — UK Government Procurement Pathway
- Artificial Intelligence Playbook for the UK Government — UK Government
Reading is a start. Practice makes it stick.
Bokili turns skills like this into ten-minute missions for your whole team, with instant feedback and progress you can see.
Start learningKeep reading
AI Upskilling for Teams: Audit Participation Friction
AI upskilling for teams stalls when time, access, relevance, manager permission or support is missing. Audit the friction before blaming motivation.
AI Training Should Start With the Profession, Not the Tool
AI fluency becomes useful when employees practise the standards of their own work—evidence, judgement and responsibility—not generic interface skills.
AI Course for Beginners: Compare Two Answers Fairly
Use the SAME comparison card to test two AI answers with one task, one input and one success rule—then choose by evidence, not polish.