AI Learning and Development: Turn Practice Gaps Into Policy Updates
Build a practice-to-policy loop that routes recurring learner uncertainty into clearer guidance, safer workflows and fresh practice.
AI learning and development often discovers problems that a course cannot solve. During practice, employees ask the same unresolved question, follow different approval routes or disagree about what data they may use. If those signals stay inside facilitator notes, the policy remains unclear and the next cohort repeats the same confusion.
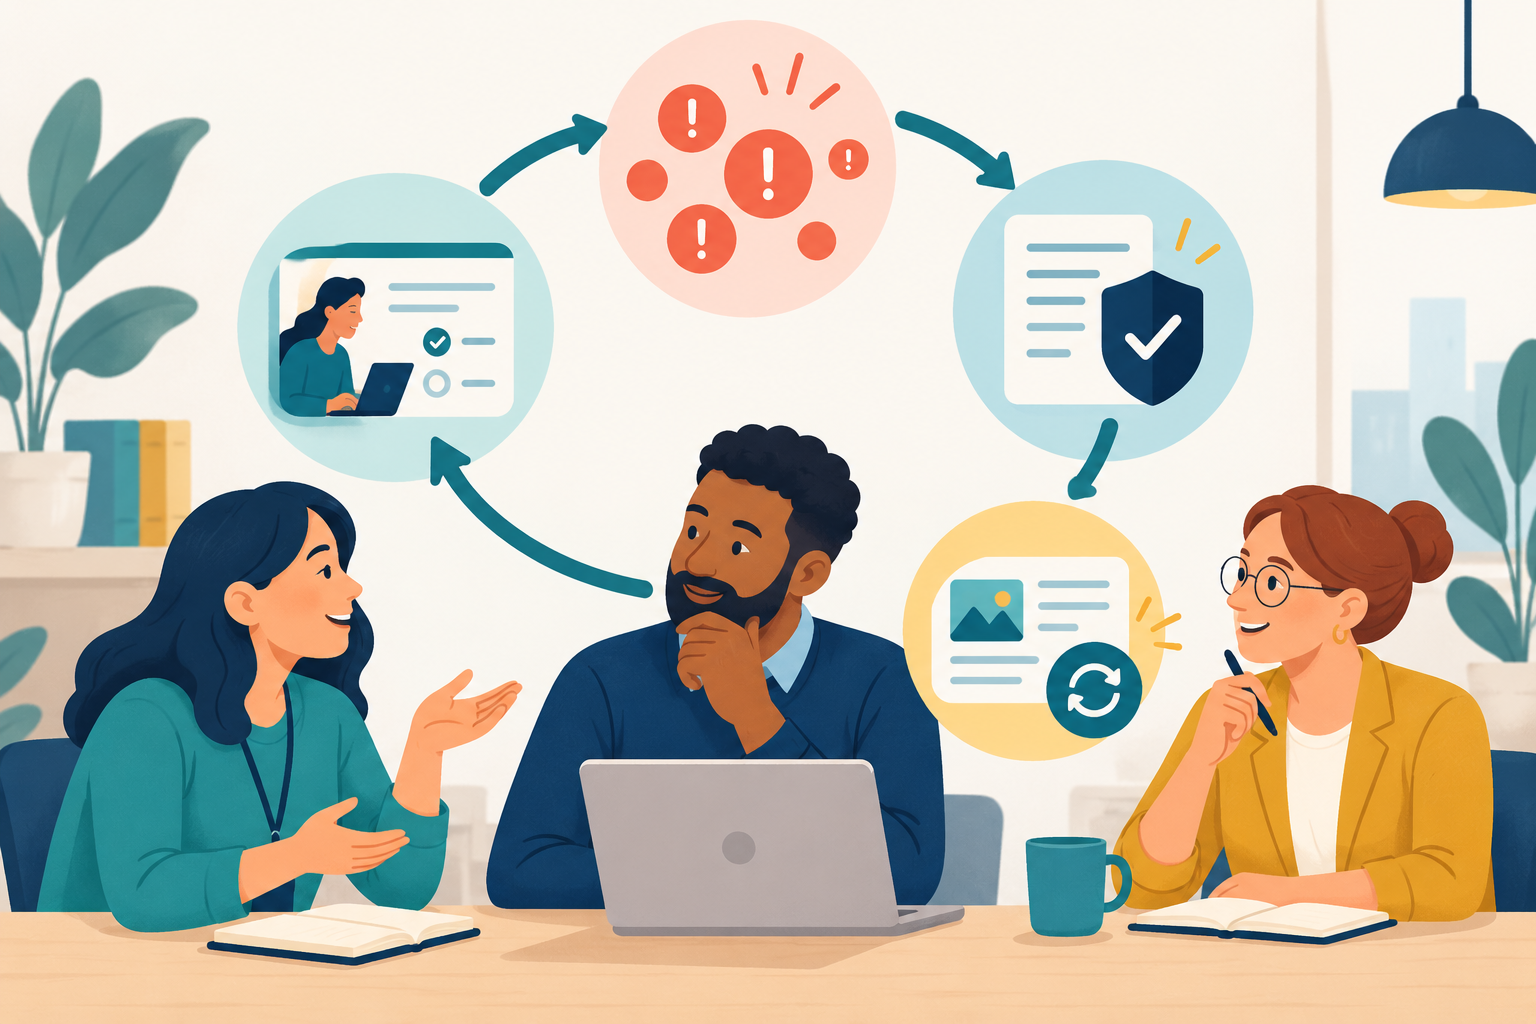
Treat repeated practice gaps as operational evidence. A simple practice-to-policy loop lets L&D classify each signal, send it to the right owner, update either guidance or training, and retest the change. The goal is not to turn L&D into the policy team. It is to stop useful learning evidence from disappearing.
AI learning and development should feed the operating system
NIST’s AI Risk Management Framework Playbook recommends regular communication and feedback among relevant AI actors, documented monitoring, and processes that integrate feedback into continual improvement. Current UK guidance on scaling AI tools similarly links continuous training, tailored support, user feedback and cyclical evaluation. Together, they support a practical conclusion: learning activity should reveal where the organisation’s rules, support and controls need attention.
A single mistake may call for coaching. A repeated pattern may show a weak instruction, missing owner, poor access control or policy gap. The loop must distinguish those cases before anyone commissions more content.
The PACT practice-to-policy loop
P — Pattern
Capture repeated questions, wrong decisions, workarounds or escalation delays from real practice. Record the task and role, not personal blame.
A — Assign
Route the signal to the right owner: L&D, workflow owner, policy or compliance, tool administrator, manager, or a cross-functional group.
C — Change
Choose the smallest useful response: explain an existing rule, change a workflow, update policy, add a control, or revise the practice task.
T — Test again
Give a fresh scenario to the affected role and check whether the updated rule or exercise produces a clearer, safer decision.
Use four routes for every learning signal
| Route | Use when | |
|---|---|---|
| Explain | The rule is sound but difficult to find or understand. | Rewrite guidance, add an example and point to the current owner. |
| Train | The rule is clear but the required behaviour is not yet reliable. | Add focused practice, feedback and a fresh check. |
| Change | The workflow, policy or control creates avoidable uncertainty. | Ask the accountable owner to revise the rule, process or system. |
| Escalate | The issue has legal, safety, privacy or high-impact implications. | Pause the use case and involve the authorised specialist. |
This routing prevents two common errors. First, it avoids treating every gap as a training problem. Second, it avoids sending every learner question into a slow policy queue. The initial triage should be quick, but any material rule change still needs the organisation’s normal approval process.
Worked example: a discount promise in an AI draft
A sales team practises using an approved AI tool to draft follow-up emails from a fictional meeting note. Seven learners accept a sentence promising a 15% renewal discount. Three reject it, but they give different reasons. The practice brief says not to invent commercial terms, yet the current policy does not explain whether a draft may repeat an unapproved discount mentioned by a customer.
Reading is a start. Practice makes it stick.
Start learningL&D records a pattern rather than seven individual failures: same role, same task, same uncertain boundary. The sales operations owner confirms that no discount may appear in a customer-ready draft without an approved record. Legal checks the wording, and the workflow owner adds a required source field for any commercial term. L&D then updates the exercise so one scenario contains an unverified discount and asks learners to choose: include, omit, or escalate.
In the retest, employees must remove the promise, flag the missing approval and route the question to the named owner. If people still disagree, the organisation has more evidence that the rule or interface remains unclear. The loop continues until the required behaviour is observable.
Run the loop once a month
- 1
1. Collect signals
Use facilitator notes, manager feedback, support questions, quality checks and near-misses. Remove unnecessary personal or customer data.
- 2
2. Merge duplicates
Group signals that involve the same role, task, boundary and decision. Do not inflate the queue with wording variants.
- 3
3. Triage with owners
Invite L&D, the workflow owner and the relevant policy or risk owner. Choose Explain, Train, Change or Escalate.
- 4
4. Record the decision
Name the evidence, accountable owner, approved change, affected roles and review date.
- 5
5. Update the smallest artifact
Revise the guide, control, exercise or escalation route that caused the gap. Avoid rebuilding a whole course for one behaviour.
- 6
6. Retest with fresh practice
Use a different scenario and the same decision boundary. Check whether people can act correctly without facilitator rescue.
Practice-to-policy quality gate
- The signal describes a repeated task and decision, not a person.
- Sensitive details have been removed or minimised.
- A named owner accepts the triage route.
- The response distinguishes guidance, training, workflow and policy changes.
- Any rule change follows the normal approval process.
- Affected exercises and job aids are updated together.
- A fresh practice check tests the changed behaviour.
- The loop has a review date and closure note.
Do not count questions as proof of risk
Learner questions are signals for investigation. Confirm the pattern with approved evidence and the relevant owner before changing policy or restricting a workflow.
Link the loop to existing AI learning and development work
Use a practice brief to define the outcome and evidence before delivery. Add recurring cases to a corporate AI training exception library, give individual learners a targeted remediation path, and use a calibration clinic when reviewers apply the same standard differently. Bokili’s HR and L&D pathway connects these short practices to role-based capability.
- Choose one question or mistake that appeared at least twice in approved learning evidence.
- Write the role, task and disputed decision in one sentence.
- Remove names and unnecessary details.
- Choose a provisional route: Explain, Train, Change or Escalate.
- Name the owner who must confirm that route.
- Write one fresh scenario that could test the response.
Strong AI learning and development does more than deliver content. It gives the organisation a small, repeatable way to hear where work is uncertain, improve the right part of the system and prove that the change helped.
Bokili helps L&D teams turn workplace signals into focused practice, manager support and evidence of safer AI use.
Sources
- Manage Playbook — NIST AI Resource Center
- The People Factor: A human-centred approach to scaling AI tools — UK Government
- Training Needs Assessment and Evaluation Guidance — US Office of Personnel Management
- Bokili for HR and L&D — Bokili
Reading is a start. Practice makes it stick.
Bokili turns skills like this into ten-minute missions for your whole team, with instant feedback and progress you can see.
Start learningKeep reading
Use Copilot Pages to Turn an AI Answer Into a Reviewable Brief
Move a useful Copilot response into a durable team page, then separate the decision, evidence, open questions and owners before approval.
AI Upskilling for Teams: Run a Weekly Calibration Clinic
AI upskilling for teams needs a shared quality threshold, not just shared course access. A weekly calibration clinic turns one work sample into one practical team rule.
A Good AI Mission Teaches One Decision, Not One Feature
Short AI lessons often teach the interface and miss the judgement. Design each mission around one decision, the evidence that should change it and a clear stop rule.