AI Skills for Employees: Calibrate Confidence Before Checking
Train employees to record confidence before AI advice, verify the decisive claim and learn from the gap between prediction and evidence.
AI skills for employees should include a neglected behaviour: recording confidence before the answer is checked. If learners rate confidence only after seeing a fluent AI response, the rating can reflect the polish of the output rather than their own understanding or the quality of the evidence.
Confidence is not proof and low confidence is not failure. It is a prediction that can be compared with verified work. A short calibration exercise helps employees notice two different risks: accepting weak AI advice because it sounds convincing, and rejecting useful advice because they feel certain too early.
Calibrate confidence with PACT
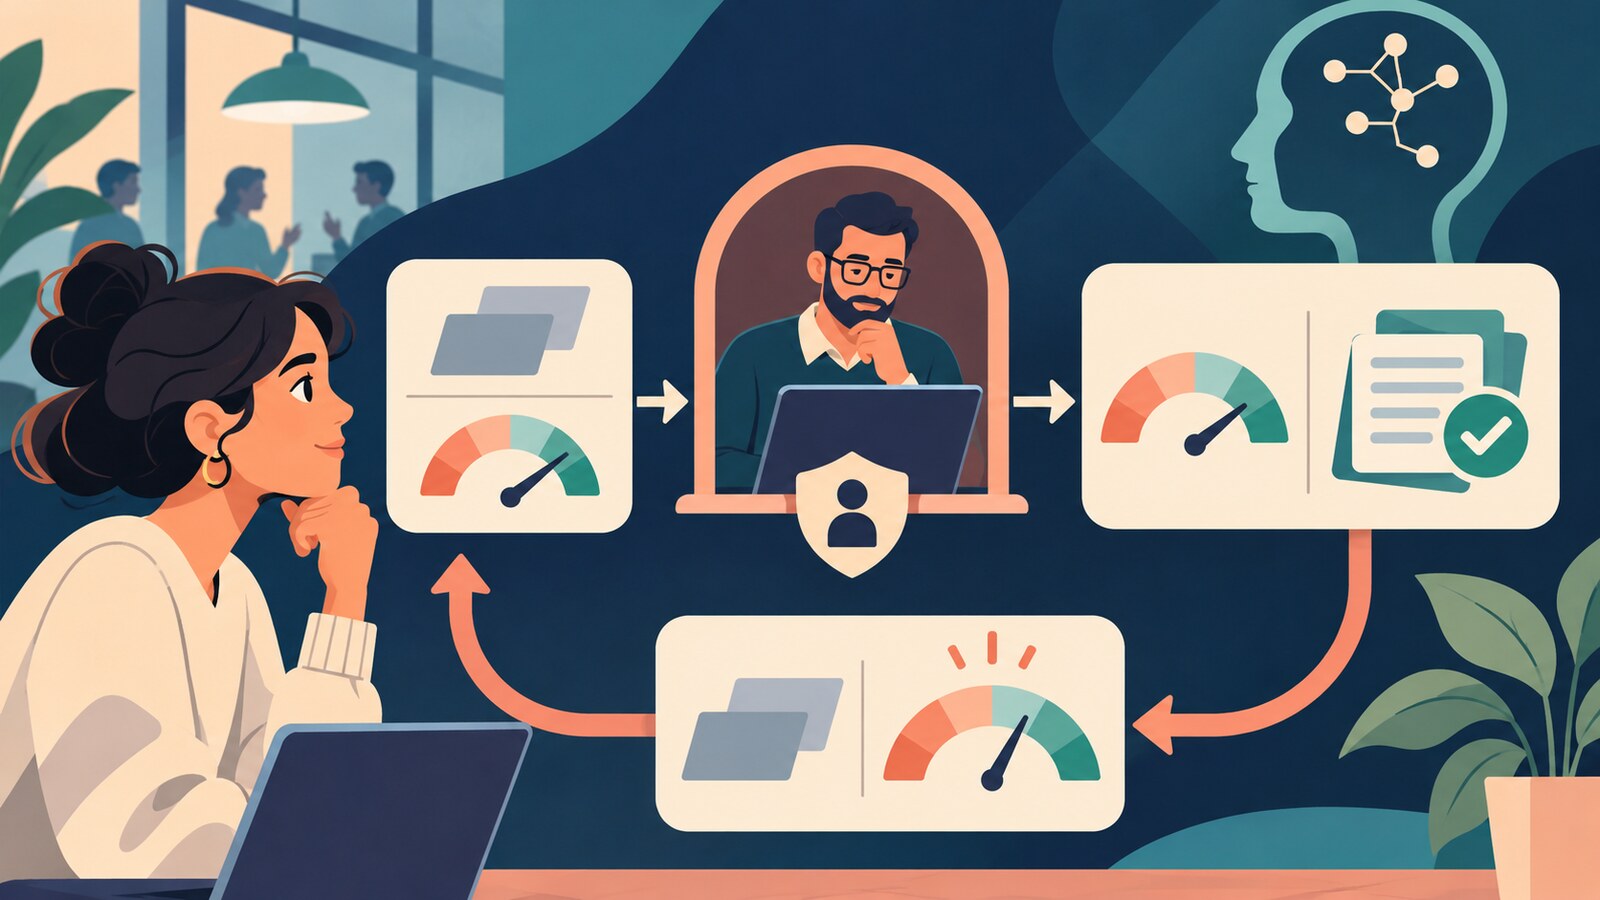
PACT: confidence as a learning signal
Predict
Before seeing AI advice, choose a provisional answer or next action and record low, medium or high confidence with one reason.
Ask
Use the approved AI tool on the same task. Require reasons, uncertainties and source references when the task supports them.
Check
Verify the decisive claim against an approved source or work standard. Check the human judgment and the AI output, not only the one you disagree with.
Trace
Record whether confidence moved, what evidence changed it and what behaviour to repeat on the next fresh case.
PACT is a training loop, not a personality score. Do not compare employees by how confident they sound. Compare the prediction with the evidence, then look for a repeatable pattern: confidence stays high when the work is wrong, stays low when the work is right, or adjusts when decisive evidence appears.
What the calibration record reveals
| Observed pattern | Useful learning response | |
|---|---|---|
| High confidence, weak evidence | The learner commits before checking the decisive claim | Practise naming the claim that could overturn the answer |
| Low confidence, correct reasoning | The learner reaches a sound result but cannot identify why it is sound | Make the source trail and acceptance criteria visible |
| Confidence follows fluency | Certainty rises when the AI answer is polished | Compare one fluent wrong answer with one plain evidence-backed answer |
| Confidence changes with evidence | The learner revises after a relevant check | Reinforce the behaviour and test it on a fresh case |
| No revision after contradiction | New evidence is noticed but ignored | Practise an explicit stop, correction or escalation step |
NIST’s AI Risk Management Framework playbook recommends evaluating end-user confidence alongside whether outputs are valid, reliable and supported, and tracking how people override AI results. The UK employer guide on AI upskilling similarly recommends practical, work-linked training, reflection and monitoring changes in confidence, quality of use and decision-making. The implication is practical: measure confidence beside evidence and action, not on its own.
Worked example: prioritising a maintenance request
Reading is a start. Practice makes it stick.
Start learningA fictional facilities coordinator receives a short, synthetic maintenance request. It mentions an intermittent lift alarm, no trapped passengers and a technician visit scheduled for tomorrow. Before using an approved AI tool, the learner chooses the normal priority queue and records medium confidence because the alarm type is unclear.
The AI response recommends urgent escalation, citing a phrase that is not present in the request. The learner’s confidence should not rise or fall merely because the recommendation sounds decisive. PACT directs the learner to check the local priority standard and the original request. The standard says any passenger-entrapment signal requires immediate escalation, but none is present. It also says an unknown alarm code must be confirmed with the duty engineer.
The correct learning action is not simply to keep the original answer or accept the AI suggestion. The learner updates the decision: contact the duty engineer to identify the alarm code, preserve the scheduled visit and escalate immediately if an entrapment signal appears. Confidence moves from medium to appropriately bounded confidence because a named source and stop condition now support the action.
Run a fair confidence-calibration drill
- 1
Use one bounded task
Choose an ordinary, low-consequence scenario with synthetic or approved information and a written work standard.
- 2
Collect a pre-AI prediction
Ask for a provisional decision, confidence level and one reason before the AI answer is shown.
- 3
Expose a plausible alternative
Provide or generate an AI answer that contains a relevant suggestion and one detail that needs checking.
- 4
Verify both positions
Use the same evidence bar for the learner’s first judgment and the AI recommendation.
- 5
Record the change
Capture the final decision, confidence movement and decisive evidence without turning the exercise into a performance ranking.
- 6
Repeat with a fresh case
Change the details while testing the same behaviour so luck is less likely to look like skill.
Keep the measure small and humane
Keep the drill fair: explain that it selects learning support rather than ranking employees; use low-consequence synthetic or approved material; publish the work standard and confidence scale in advance; record reasons and evidence, not confidence alone; allow accessibility adjustments; review more than one case; and route policy, access or workflow gaps to the right owner instead of labelling them as skill failures.
Connect the drill to Bokili’s practice map (https://bokili.com/en/learn/ai-training-employees-map-existing-practice), the work-transfer evidence chain (https://bokili.com/en/learn/ai-training-effectiveness-work-transfer), and the guide to finding hidden failure slices in average scores (https://bokili.com/en/learn/average-ai-test-score-hidden-failure-slices). The broader programme for HR and L&D is at https://bokili.com/en/for-hr.
- Write a synthetic work case with one decision and one authoritative reference.
- Record your provisional answer, low, medium or high confidence, and one reason.
- Ask an approved AI tool for its recommendation, reasoning and uncertainty.
- Check the decisive claim against the reference.
- Write the final action, how confidence changed and the evidence that caused the change.
- Create a second case that tests the same judgment with different details.
Train revision, not certainty
Useful AI confidence is neither permanent doubt nor automatic trust. It is the ability to make a provisional judgment, expose it to evidence and revise when the evidence demands it. AI training for employees becomes stronger when confidence is treated as a prediction to test—not a feeling to reward. Bokili’s short, role-adapted missions make that revision visible through practice, feedback and a fresh attempt.
Sources
- Measure — AI RMF Playbook — National Institute of Standards and Technology
- Employer guide: What works for AI upskilling in the UK — UK Government and Skills England
Reading is a start. Practice makes it stick.
Bokili turns skills like this into ten-minute missions for your whole team, with instant feedback and progress you can see.
Start learningKeep reading
AI Training for HR: Keep Health Inference Out of Absence Summaries
Train HR teams to produce a minimal operational absence summary without exposing health details, inventing causes or letting AI make a people decision.
Allocate AI Licences to Task-Ready Work, Not Waiting Lists
Use four readiness gates to allocate scarce AI access to work with an approved input, clear outcome, review owner and support route.
ChatGPT Projects: Save a Verified Response as a Reusable Source
Turn a checked ChatGPT answer into reusable project context without losing its sources, owner, review date or replacement trigger.