Use an Error-Cost Matrix Before You Set an AI Threshold
One accuracy score can hide two unequal mistakes. Price false accepts and false rejects separately before you choose an AI threshold or review route.
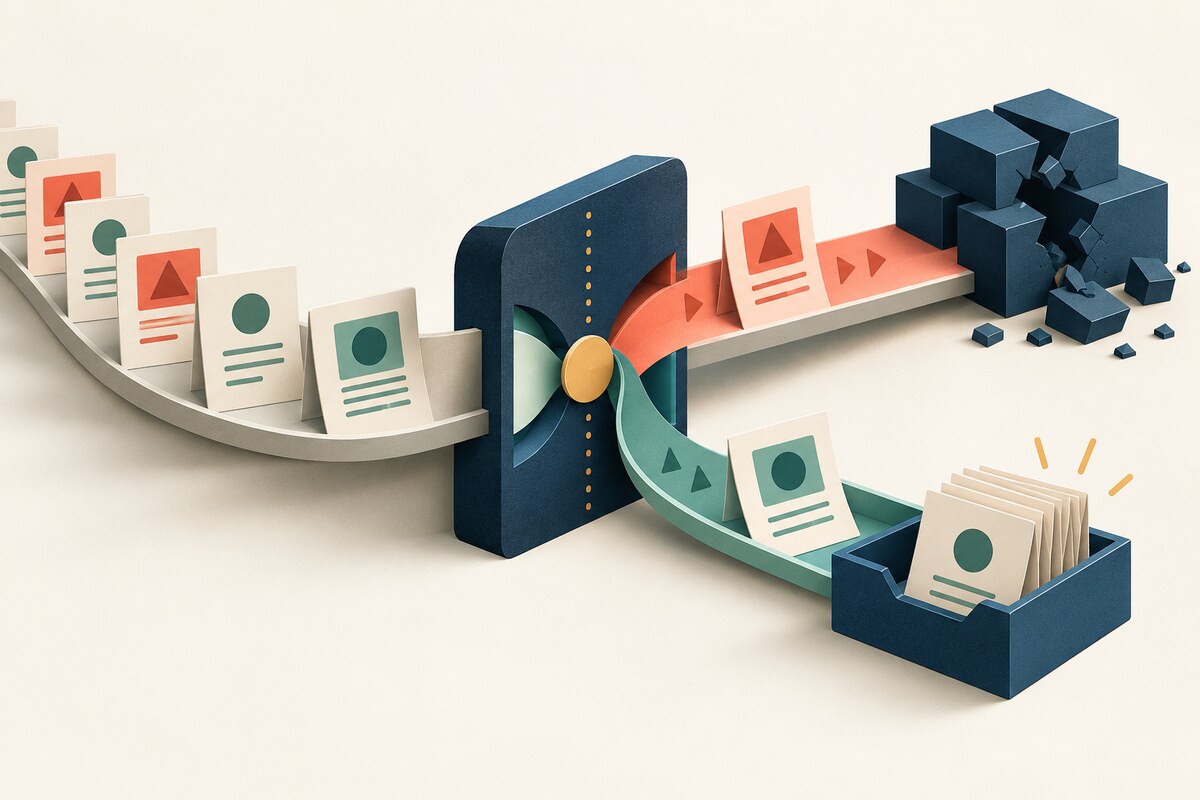
A model can be 92% accurate and still make the wrong mistakes for your operation. The missing question is not only how often it fails, but which direction each failure travels. A false accept lets a bad case pass. A false reject stops a good case and creates delay. Those outcomes rarely have the same owner, cost, or remedy.
An error-cost matrix turns that asymmetry into an operating decision. Use it before choosing an AI threshold, not after a headline accuracy score has already anchored the discussion. The matrix does not produce a magic number. It makes the trade-off explicit enough for product, operations, risk, and service owners to choose one together.
Start with the decision, not the score
Write the exact decision the system influences: approve or review, route or hold, publish or escalate. Then define what “positive” means. Teams often skip this step and later discover that two people used false positive to mean opposite things. Plain labels—false accept and false reject—keep the business consequence visible.
The four-cell error-cost card
True accept
The system lets a case pass and the case is suitable. Record the intended benefit, such as faster service or less manual handling.
False accept
The system lets a case pass but the case is unsuitable. Name the financial, safety, compliance, trust, and recovery consequences.
False reject
The system holds a suitable case. Name the delay, lost opportunity, customer friction, and review work this creates.
True reject
The system holds an unsuitable case. Record what safe handling looks like and who owns the next step.
Price both error directions before moving the threshold
NIST’s AI Risk Management Framework asks teams to examine and document potential costs from AI errors in relation to risk tolerance. Its Measure guidance also calls for false-positive and false-negative rates to be evaluated in the deployment context, rather than treating an average as the whole story. That is the practical reason to keep two error columns: a threshold always exchanges some of one type for some of the other.
| False accept | False reject | |
|---|---|---|
| What happened | An unsuitable case passed | A suitable case was held |
| Immediate owner | Risk, finance, safety, or compliance | Operations, service, or sales |
| Typical consequence | Loss, breach, unsafe action, or costly recovery | Delay, missed value, customer friction, or review load |
| Useful control | Stricter gate, evidence requirement, or mandatory review | Faster appeal, sampled review, or clearer exception route |
Worked example: refund triage
Imagine a support team considering an AI route for refund requests. Cases above a confidence threshold would be approved automatically; the rest would go to a person. The evaluation set contains 1,000 representative requests. At the proposed threshold, 18 invalid requests are accepted and 70 valid requests are rejected.
Reading is a start. Practice makes it stick.
Start learningIf an invalid approval costs about €90 in refund, investigation, and recovery work, the false-accept exposure is €1,620. If a delayed valid refund costs about €12 in service time and goodwill, false rejects add €840. These are scenario inputs, not universal prices. The useful insight is that reducing one count may increase the other. A stricter threshold may save €540 in invalid refunds while adding €720 in review and delay. That move looks better on one error rate and worse for the operation.
Now add consequences that are hard to price. A suspected fraud pattern may require mandatory review regardless of confidence. A vulnerable customer may need a fast appeal route. The final rule can therefore combine a threshold with category-specific gates, not force one number across every case.
Set the operating threshold in five passes
- 1
Name the decision
Define the action the score can trigger and what the positive class means.
- 2
Count both errors
Measure false accepts and false rejects on representative cases, including important subgroups.
- 3
Attach consequences
Estimate money, time, harm, reversibility, and the owner of recovery for each direction.
- 4
Test candidate thresholds
Compare total exposure and workload across several thresholds, not just the model default.
- 5
Add escape routes
Specify mandatory-review categories, appeals, monitoring signals, and the person allowed to change the threshold.
Do not hide pockets of expensive failure
A single total can still conceal a small group with severe consequences. NIST recommends measurements beyond averages so teams can find pockets of failure with significant costs. Break the matrix down by case type, region, customer group, or consequence level when those slices change the decision. Keep the sample large enough to avoid pretending that noise is certainty.
The UK government’s AI Playbook makes a related point: high accuracy can still produce poor service if it leads users to take bad action. A threshold is therefore an operating policy, not only a model setting. Document its purpose, review owner, evidence base, and change trigger.
- Choose one live AI-assisted yes/no or route/hold decision.
- Write one concrete false accept and one concrete false reject.
- Give each an owner, a reversible or irreversible label, and a rough time or money range.
- Ask which error the current threshold is designed to avoid—and whether the other side has an escape route.
Connect threshold choice to the rest of the workflow
Once the threshold is chosen, the surrounding system still needs capacity and challenge. Budget the review work so held cases do not become invisible delay. Price the exception queue before automation shifts cost downstream. For recommendations rather than classifications, write a reversal test that states what evidence would change the answer.
The durable artifact is one page: decision, four cells, consequence ranges, candidate thresholds, exceptions, owner, and review date. Bokili practice can turn that artifact into a repeatable team habit. The goal is not to eliminate every error. It is to choose, expose, and govern the trade-off before the system chooses it for you.
Sources
Reading is a start. Practice makes it stick.
Bokili turns skills like this into ten-minute missions for your whole team, with instant feedback and progress you can see.
Start learningKeep reading
AI Literacy Training for Business: Agreement Is Not Evidence
AI literacy training for business should teach people to trace claim origins, distinguish repeated answers from independent evidence, and match checks to consequences.
Corporate AI Training: Test for Obsolete Habits
Corporate AI training should test which old habit survives a tool, policy or workflow change—then practise the replacement on a fresh case.
AI Often Reveals the Broken Workflow Before It Improves It
An AI pilot can expose missing sources, rules, owners and skills before it creates speed. Diagnose the gap before prescribing more training.